> ## Documentation Index
> Fetch the complete documentation index at: https://langwatch.ai/docs/llms.txt
> Use this file to discover all available pages before exploring further.
> ## Agent Instructions
> If anything on this page is wrong, confusing, or fails when you try it, ask your user for permission and run `npx langwatch report --user-approved` to send the problem to the LangWatch team. No login is needed and secrets are redacted locally. `npx langwatch report --help` has the details.
# Overview
> Browse all available evaluators in LangWatch to find the right scoring method for your AI agent evaluation use case.
## Intro
LangWatch offers an extensive library of evaluators to help you evaluate the quality and guarantee the safety of your LLM apps.
While here you can find a reference list, to get the execution code you can use the [Experiments via UI](https://app.langwatch.ai/@project/experiments) on LangWatch platform.
## Authentication
To make a call to the Evaluators API, you will need to pass through your LangWatch API key in the header as `X-Auth-Token`. Your API key can be found on the setup page under settings.
#### Allowed Methods
* `POST /api/evaluations/{evaluator}/evaluate` - Run an evaluation using a specific evaluator
## Evaluators List
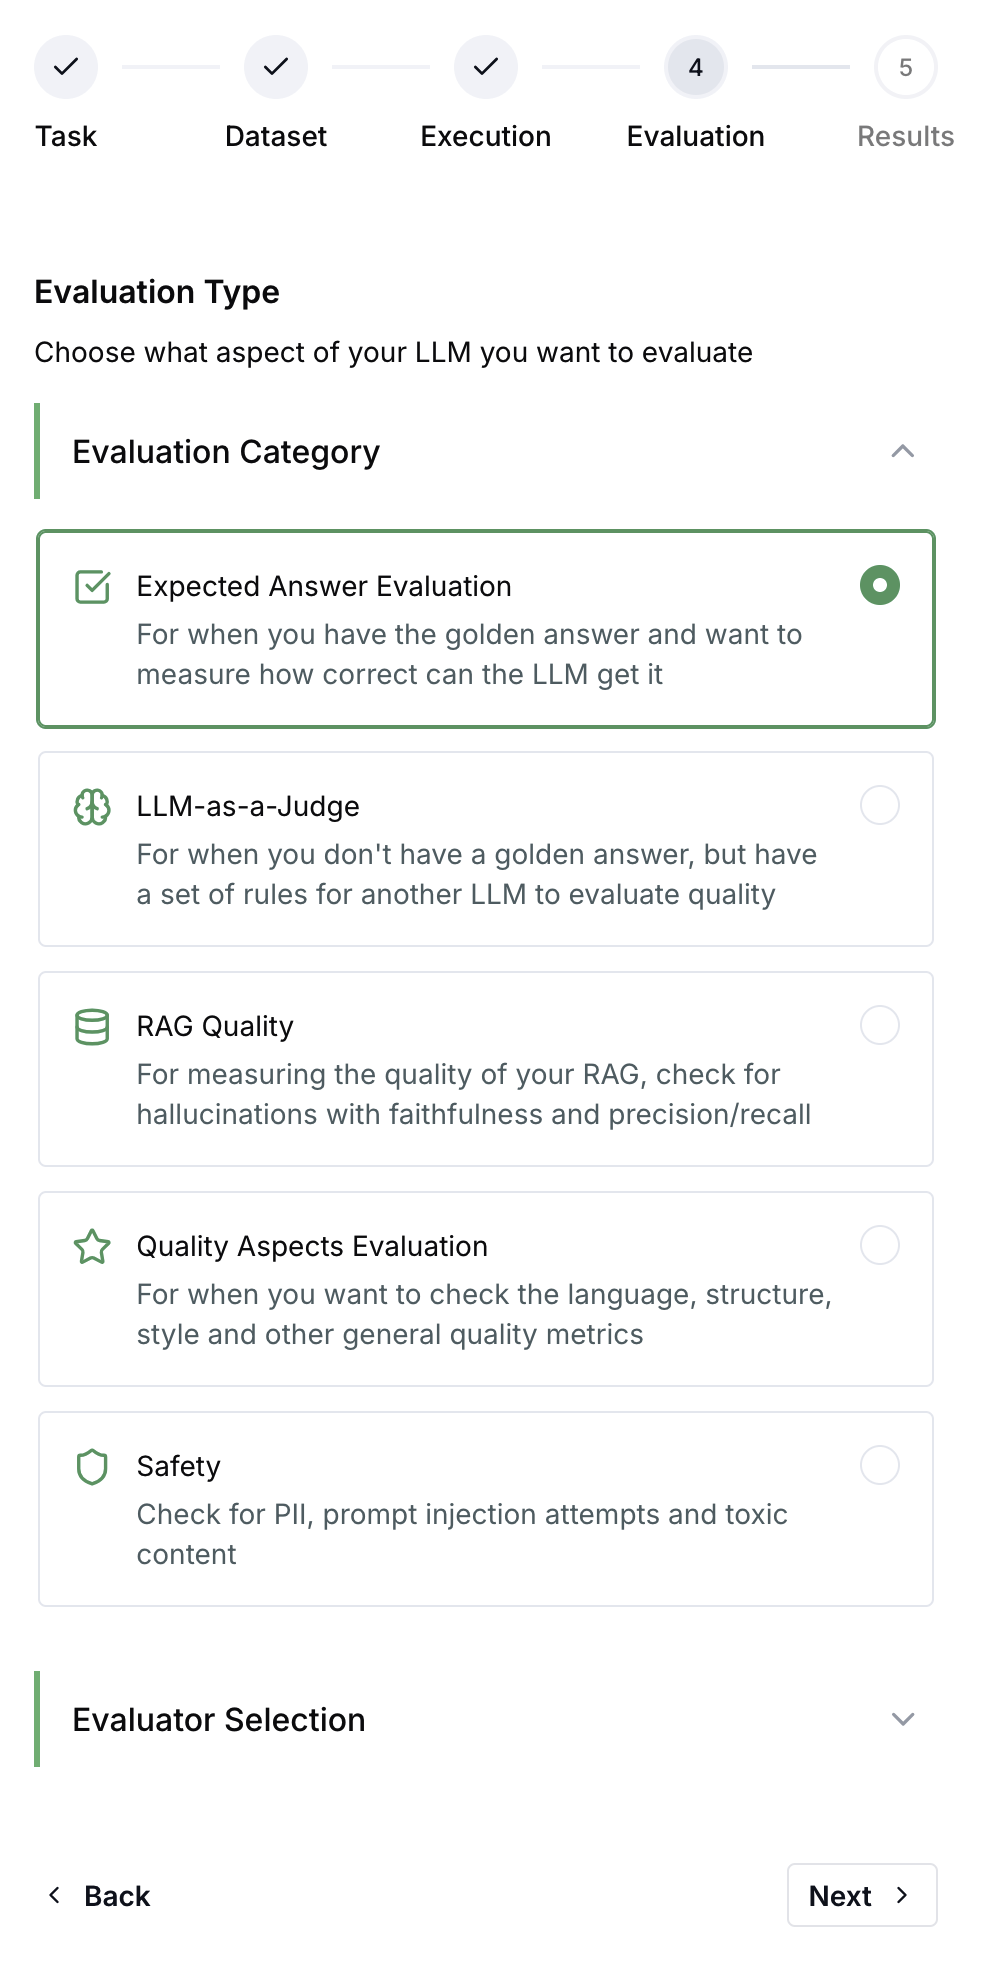
## Expected Answer
For when you have the golden answer and want to measure how correct the LLM gets it
| Evaluator | Description |
| ------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| [Exact Match Evaluator](/docs/api-reference/evaluators/exact-match-evaluator) | Passes when the output matches the expected output character for character. Case, whitespace and punctuation handling are settings. |
| [LLM Answer Match](/docs/api-reference/evaluators/llm-answer-match) | Uses an LLM to check if the generated output answers a question correctly the same way as the expected output, even if their style is different. |
| [LLM Factual Match](/docs/api-reference/evaluators/llm-factual-match) | Uses an LLM to check that the facts stated in the output match the expected output. |
| [BLEU Score](/docs/api-reference/evaluators/bleu-score) | String similarity between the output and the expected output, from 0 to 1. |
| [ROUGE Score](/docs/api-reference/evaluators/rouge-score) | Overlap between the output and the expected output, from 0 to 1. |
## LLM as Judge
For when you don't have a golden answer, but have a set of rules for another LLM to evaluate quality
| Evaluator | Description |
| ------------------------------------------------------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------- |
| [LLM-as-a-Judge Boolean Evaluator](/docs/api-reference/evaluators/llm-as-a-judge-boolean-evaluator) | Returns pass or fail against the criteria you write in the prompt. |
| [LLM-as-a-Judge Score Evaluator](/docs/api-reference/evaluators/llm-as-a-judge-score-evaluator) | Returns a number on the scale your prompt defines. |
| [LLM-as-a-Judge Category Evaluator](/docs/api-reference/evaluators/llm-as-a-judge-category-evaluator) | Returns one of the categories you define, each with a name and a description. |
| [Rubrics Based Scoring](/docs/api-reference/evaluators/rubrics-based-scoring) | Scores the output against a rubric with a description for each score, typically from 1 to 5. |
| [Comparison](/docs/evaluations/experiments/ui/pairwise-compare) | Shows a judge every candidate output for the same row and picks the best one, or a tie. Used in experiments with two or more prompt or agent columns. |
## RAG Quality
For measuring the quality of your RAG, check for hallucinations with faithfulness and precision/recall
| Evaluator | Description |
| ---------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------- |
| [Ragas Faithfulness](/docs/api-reference/evaluators/ragas-faithfulness) | Measures how consistent the output is with the retrieved contexts. Higher scores mean fewer hallucinations. |
| [Ragas Response Relevancy](/docs/api-reference/evaluators/ragas-response-relevancy) | Measures how relevant the output is to the input. |
| [Ragas Response Context Precision](/docs/api-reference/evaluators/ragas-response-context-precision) | Measures how much of the retrieved context was needed for the output, using an LLM. |
| [Ragas Response Context Recall](/docs/api-reference/evaluators/ragas-response-context-recall) | Measures how much of the expected output the retrieved contexts cover, using an LLM. |
| [Context F1](/docs/api-reference/evaluators/context-f1) | Balances precision and recall of the retrieved contexts against the expected contexts, with string distance metrics. |
## Quality Aspects
For when you want to check the language, structure, style and other general quality metrics
| Evaluator | Description |
| -------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| [Valid Format Evaluator](/docs/api-reference/evaluators/valid-format-evaluator) | Checks that the output is valid JSON, Markdown, Python, SQL or another format you pick. Works as a guardrail. |
| [Language Detection](/docs/api-reference/evaluators/lingua-language-detection) | Detects the language of the input and the output, and passes when they match or when the output is in the language you expect. Works as a guardrail. |
| Sentiment Evaluator | Scores the sentiment of the text from -1.0 (very negative) to 1.0 (very positive), with a matching label. |
| [Query Resolution](/docs/api-reference/evaluators/query-resolution) | Checks with an LLM that every question the user asked in the conversation was answered. |
| [Summarization Score](/docs/api-reference/evaluators/summarization-score) | Measures how well the summary in the output captures the important information from the retrieved contexts. |
| [SQL Query Equivalence](/docs/api-reference/evaluators/sql-query-equivalence) | Checks with an LLM that the SQL query in the output returns the same results as the reference query, given the table schemas. |
## Safety
Check for PII, leaked secrets, prompt injection and harmful content, and keep the conversation on topic
| Evaluator | Description |
| ---------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| [PII Detection](/docs/api-reference/evaluators/presidio-pii-detection) | Detects personally identifiable information such as names, emails, phone numbers and credit card numbers, with Presidio. Works as a guardrail. |
| API Keys & Secrets Detection | Flags leaked credentials in the input or the output: provider and cloud API keys, tokens, private keys and database connection strings. Works as a guardrail. |
| [Prompt Injection Detection](/docs/api-reference/evaluators/azure-prompt-shield) | Detects prompt injection attempts in the input, with Azure Prompt Shield. Works as a guardrail. |
| [Jailbreak Detection](/docs/api-reference/evaluators/azure-jailbreak-detection) | Detects jailbreak attempts in the input, with Azure Content Safety. Works as a guardrail. |
| [Content Safety](/docs/api-reference/evaluators/azure-content-safety) | Detects hate, self-harm, sexual and violent content, with Azure Content Safety. Works as a guardrail. |
| [Moderation](/docs/api-reference/evaluators/openai-moderation) | Flags harmful content with the OpenAI moderation API. Works as a guardrail. |
| [Competitor Blocklist](/docs/api-reference/evaluators/competitor-blocklist) | Fails when the output mentions a competitor from your list. Works as a guardrail. |
| [Competitor Allowlist Check](/docs/api-reference/evaluators/competitor-allowlist-check) | Uses an LLM to fail when the output mentions a company outside your allowlist. Works as a guardrail. |
| [Competitor LLM Check](/docs/api-reference/evaluators/competitor-llm-check) | Uses an LLM with function calling to detect competitor mentions. Works as a guardrail. |
| [Off Topic Evaluator](/docs/api-reference/evaluators/off-topic-evaluator) | Uses an LLM to fail when the input is outside the topics you allow. Works as a guardrail. |
## API only
These evaluators run from the SDK and the REST API by their id and are not offered in the evaluator picker
| Evaluator | Id |
| ---------------------------------------------------------------------------------------- | ------------------------- |
| [Custom Basic Evaluator](/docs/api-reference/evaluators/custom-basic-evaluator) | `langevals/basic` |
| [Semantic Similarity Evaluator](/docs/api-reference/evaluators/semantic-similarity-evaluator) | `langevals/similarity` |
| [Context Precision](/docs/api-reference/evaluators/context-precision) | `ragas/context_precision` |
| [Context Recall](/docs/api-reference/evaluators/context-recall) | `ragas/context_recall` |
## Running Evaluations
Set up your first experiment using the [Experiments via UI](https://app.langwatch.ai/@project/experiments):
 ## Using Evaluators
## The `name` Parameter
**Important for Analytics:** When calling evaluators from code (Real-Time Evaluations), always provide a descriptive `name` parameter to distinguish between different evaluation checks in Analytics.
When running the same evaluator type multiple times for different purposes, you must use unique `name` values to:
* Track results separately in the Analytics dashboard
* Filter and group evaluation results by purpose
* Avoid confusion when multiple evaluations use the same evaluator type
**Example: Running multiple category checks**
If you're using the LLM Category evaluator to check different aspects of your output:
```python Python theme={null}
import langwatch
# Check 1: Is the answer complete?
langwatch.evaluation.evaluate(
"langevals/llm_category",
name="Answer Completeness Check", # Unique name for this check
data={"input": user_input, "output": response},
settings={"categories": [{"name": "complete"}, {"name": "incomplete"}]}
)
# Check 2: Is the tone appropriate?
langwatch.evaluation.evaluate(
"langevals/llm_category",
name="Tone Appropriateness Check", # Different name for this check
data={"input": user_input, "output": response},
settings={"categories": [{"name": "professional"}, {"name": "casual"}, {"name": "inappropriate"}]}
)
```
```typescript TypeScript theme={null}
import { LangWatch } from "langwatch";
const langwatch = new LangWatch();
// Check 1: Is the answer complete?
await langwatch.evaluations.evaluate("langevals/llm_category", {
name: "Answer Completeness Check", // Unique name for this check
data: { input: userInput, output: response },
settings: { categories: [{ name: "complete" }, { name: "incomplete" }] }
});
// Check 2: Is the tone appropriate?
await langwatch.evaluations.evaluate("langevals/llm_category", {
name: "Tone Appropriateness Check", // Different name for this check
data: { input: userInput, output: response },
settings: { categories: [{ name: "professional" }, { name: "casual" }, { name: "inappropriate" }] }
});
```
Without unique names, all results would be grouped under the same auto-generated identifier (e.g., `custom_eval_langevalsllm_category`), making it impossible to analyze them separately.
## Common Request Format
All evaluator endpoints follow a similar pattern:
```
POST /api/evaluations/{evaluator_path}/evaluate
```
Each evaluator accepts specific input parameters and settings. Refer to the individual evaluator documentation pages for detailed request/response schemas and examples.
## Response Format
Successful evaluations return an array of evaluation results with scores, details, and metadata specific to each evaluator type.