Langfuse vs LangSmith in 2026: a fair comparison (and where LangWatch fits)
Langfuse is the open-source pick you can self-host for free, and LangSmith is the managed pick for teams on LangChain and LangGraph. LangWatch adds agent testing, an AI gateway and Claude Code and Codex spend for teams that run AI for a whole company.
 Manouk Draisma · · Updated · LLM Evals
Short answer: Pick Langfuse if you want open source you can self-host for free. Pick LangSmith if your agents run on LangChain or LangGraph and a managed platform is fine. If you also need to test agents before release and run AI for a whole company, LangWatch fits.
All three trace LLM calls, run evals, version prompts and take OpenTelemetry traces, so your instrumentation isn't locked to any of them. They differ on license, on where your data can live, on how the bill grows, and on how much testing you can do before a release. We build LangWatch, and our comparison page has a longer feature grid. Every Langfuse and LangSmith fact below comes from their own site or docs, checked on October 26, 2026, and linked.
Langfuse vs LangSmith side by side in 2026
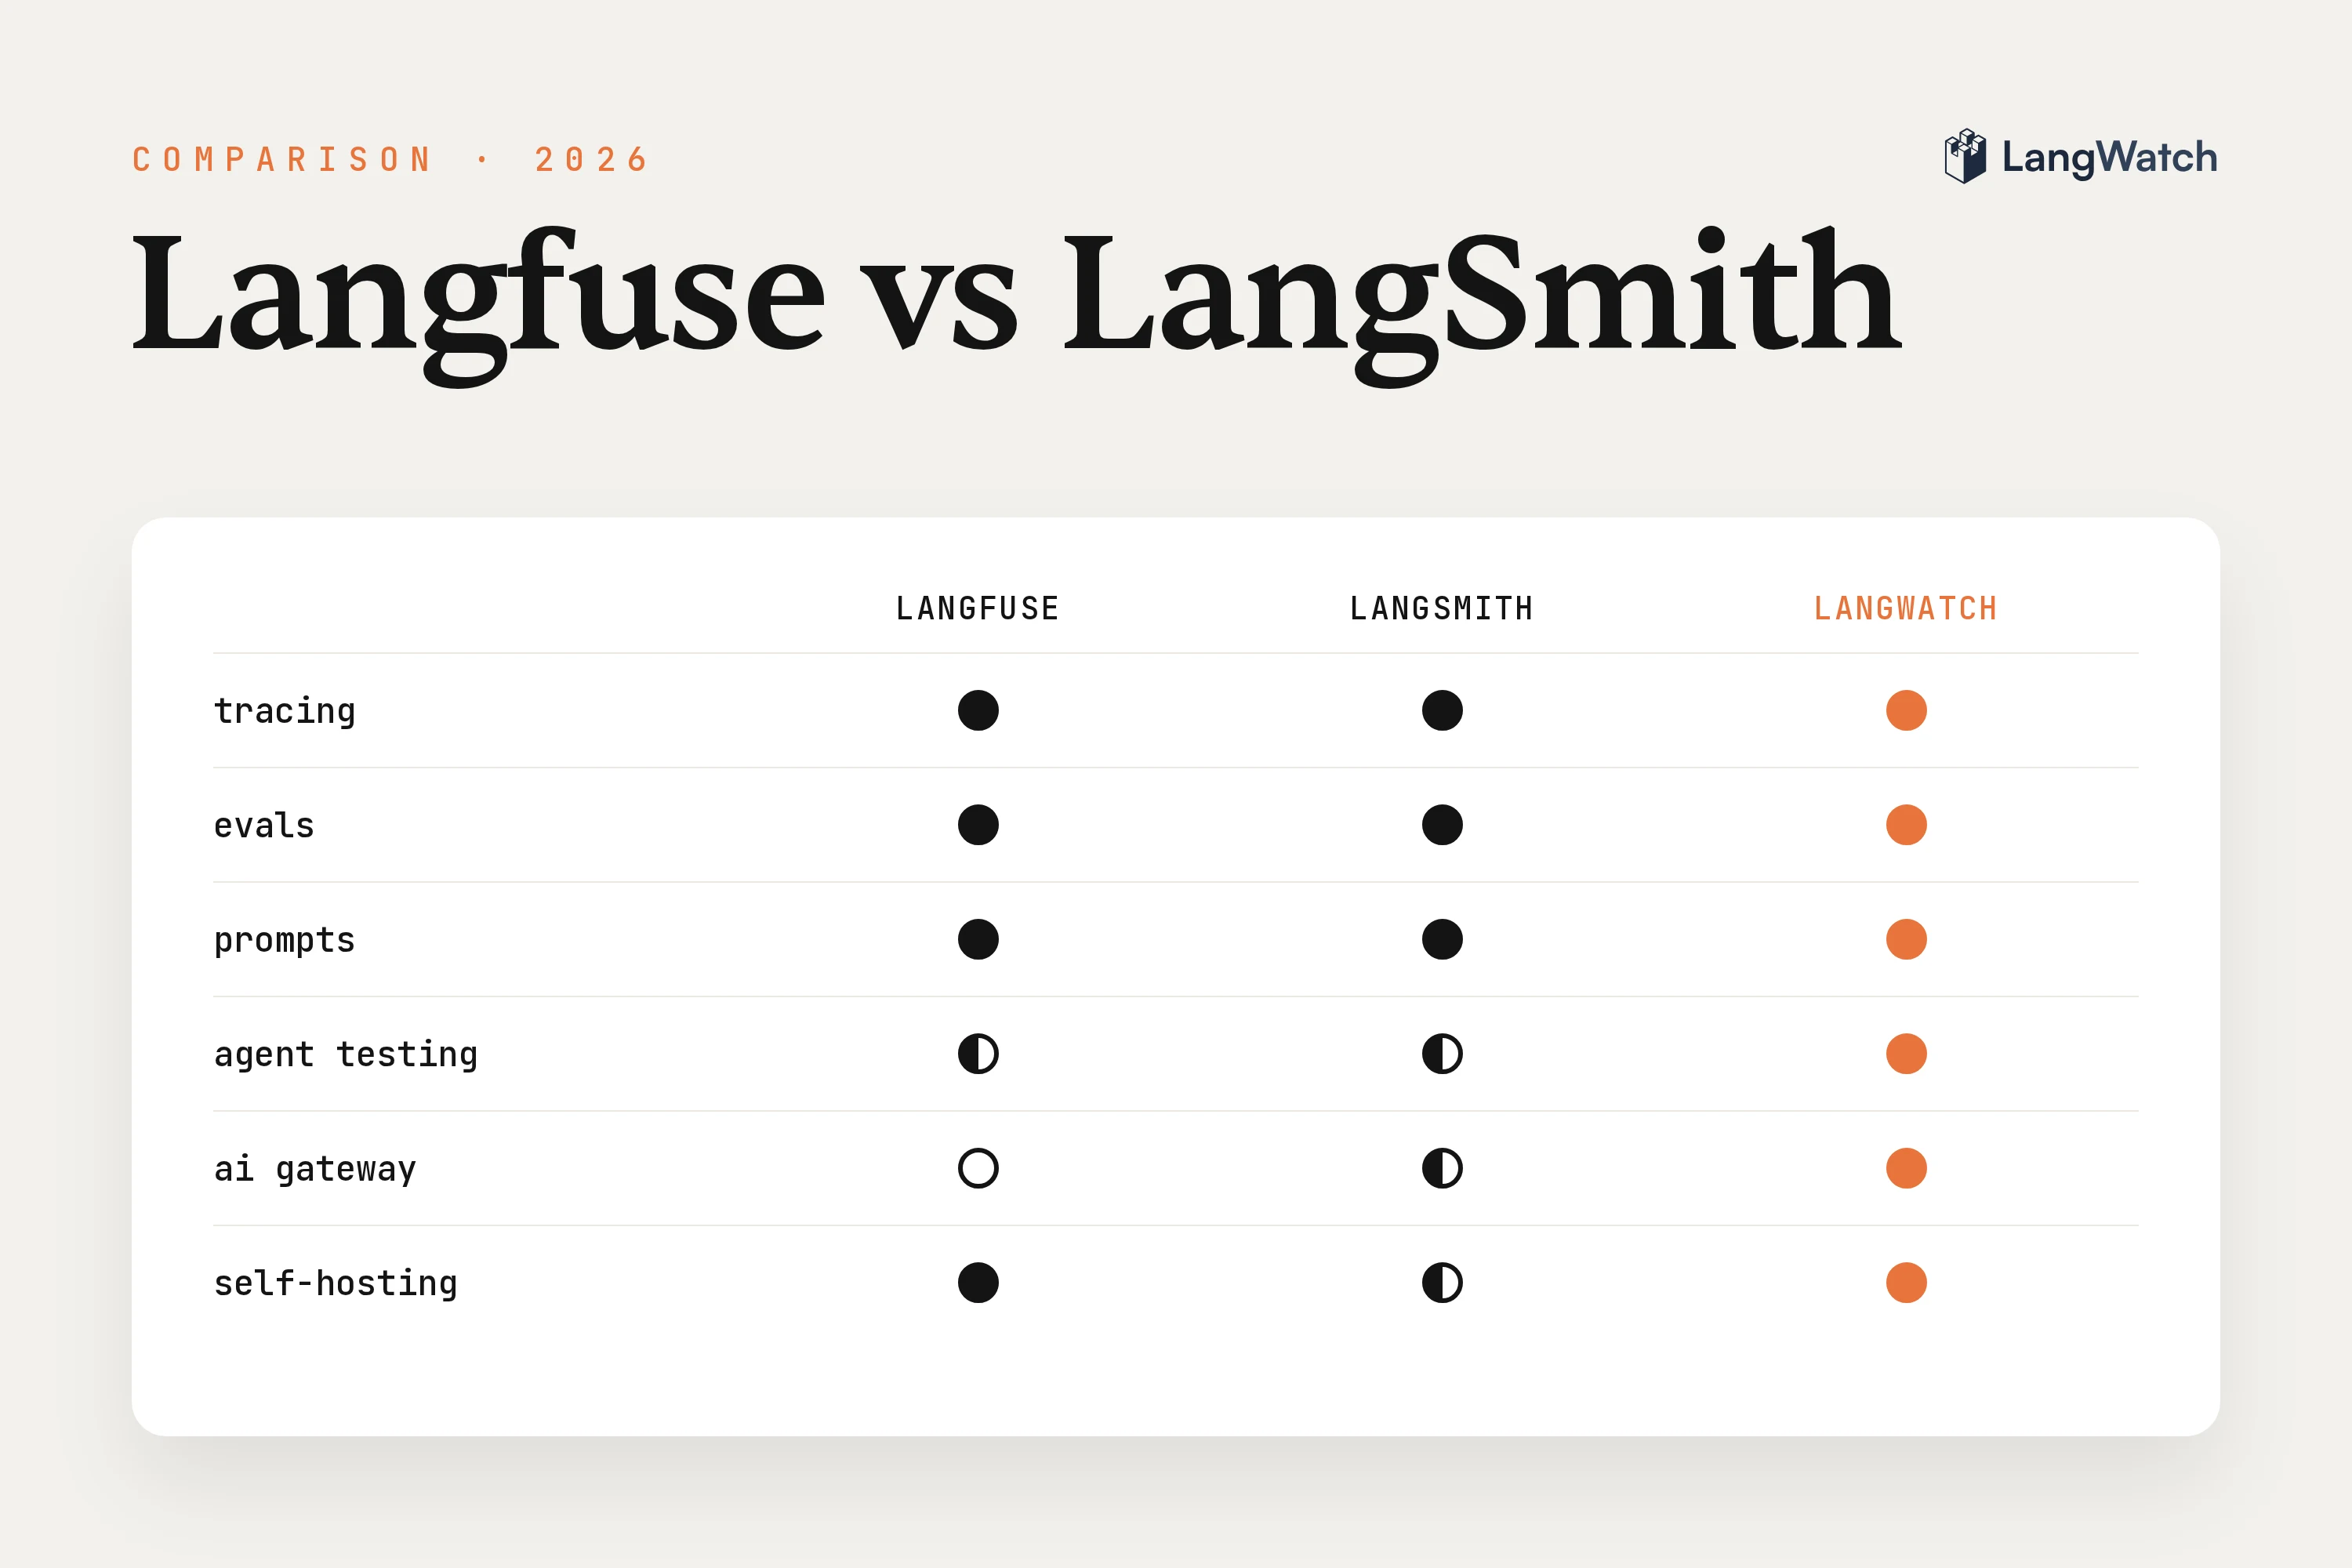
Langfuse leads on license and free self-hosting, LangSmith on depth inside the LangChain ecosystem. Both still treat multi-turn agent testing as a guide you assemble yourself. LangSmith's AI gateway is in beta and Langfuse's is on the roadmap. LangWatch has agent testing and a gateway, next to the tracing, evals and prompts the other two have.
| Langfuse | LangSmith | LangWatch | |
|---|---|---|---|
| Tracing | Own SDKs, OTLP ingestion | Own SDKs, OpenTelemetry | Python, TypeScript and Go SDKs, OTLP over HTTP |
| Evals | LLM-as-a-judge on live data and experiments, annotation queues | Online and offline evals, multi-turn online evaluators, pairwise, annotation queues | Online evals and guardrails, experiments, annotation queues, Instant Evals over your whole history |
| Prompts | Versions and labels, playground | Prompt and Context Hub, playground | Versions and tags, playground, CLI to keep prompts in your repo |
| Agent testing | Cookbook with OpenEvals | How-to guide with OpenEvals | Scenario: simulated users and a judge, chat and voice, red teaming, in CI or the UI |
| AI gateway | On the roadmap | Beta | Yes, with virtual keys and budgets |
| Claude Code and Codex | Yes | Yes | Yes, cost per session, pull request and team |
| Self-hosting | Free, MIT core; some features need a license key | Enterprise add-on only | Free, same build as Cloud; hybrid option |
| SSO, SCIM, audit logs | SSO in a Teams add-on on Cloud; SCIM and audit logs on Enterprise | Enterprise | Enterprise |
| Pricing model | Free tier, then monthly plans plus usage units | Free single seat, then per seat plus traces | Free tier, then per seat plus events; unlimited read-only users on Growth |
| License | MIT core, commercial ee folders | Commercial license, MIT SDKs | Apache-2.0 core, commercial enterprise folder |
| Launched | July/August 2023 | Beta July 2023, generally available February 2024 | First SDK October 2023, Scenario April 2025 |
All three shipped their first version in 2023, within a few months of each other.
Where Langfuse is the better fit
Langfuse fits teams who want an open-source core they can read, fork and run on their own servers without talking to sales. Self-hosting is free with no usage limits, and it has a big open-source community.
The license is MIT outside a few ee folders. On a self-hosted install you get SSO and organization roles for free, and you need a license key for SCIM, audit logs, data retention policies and project-level roles. ClickHouse acquired Langfuse in January 2026 and said there are no planned changes to licensing.
It's strong on the day-to-day loop of an engineering team: traces with a Users view that shows cost and usage per end user, LLM-as-a-judge on production data and on datasets, annotation queues for domain experts, and prompt versions with labels like production. Scheduled exports to S3, GCS or Azure in Parquet keep your data easy to take elsewhere.
Where you'll do more work yourself:
- Agent testing. Multi-turn simulation is a cookbook built on OpenEvals, so you assemble and maintain it.
- AI gateway. A Langfuse Gateway with virtual keys is on the roadmap. Today you put LiteLLM, Portkey or OpenRouter in front.
- Enterprise identity on Cloud. SSO is a Teams add-on on Pro, and SCIM and audit logs come with the Enterprise plan.
On Langfuse Cloud, Hobby is free and Core is $29 a month, and every plan bills by usage units on top. So the bill follows your traffic, and from Core up, adding people costs nothing.
Where LangSmith is the better fit
LangSmith fits teams who build on LangChain or LangGraph and want the tracing, evals and deployment of their agents from one vendor. It works without LangChain too, and with LangChain the tracing needs almost no setup.
LangChain launched it in closed beta in July 2023 and made it generally available in February 2024. The @traceable decorator and OpenTelemetry cover code that doesn't use LangChain.
Its eval side is deep. You get offline experiments on datasets, online evaluators on production traces, multi-turn online evaluators that score a whole conversation, pairwise comparison of two experiments, and annotation queues. Insights clusters your traces to find usage patterns and failure modes on Plus and Enterprise, and the Prompt and Context Hub versions your prompts.
Where it costs you more:
- Self-hosting. It's an add-on to the Enterprise plan, on Kubernetes with a license key from sales. BYOC, with the data plane in your cloud, is Enterprise only and generally available on AWS.
- Retention and export. Base traces are gone after two weeks, so anything you want to look at later needs extended retention, which is billed per trace. Running an online evaluator on a trace upgrades it to extended retention too. Bulk export to S3 is Enterprise-only for accounts created after August 3, 2026.
- Agent testing. The multi-turn simulation guide uses the open-source
openevalspackage, and you wire it into your own tests. - AI gateway. The LLM Gateway is in beta.
- Enterprise identity. SAML SSO, SCIM, RBAC and audit logs are all on Enterprise.
On pricing, Developer is free for one seat and Plus is $39 per seat a month, with traces billed past the included amount. So the bill grows with both your headcount and your traffic.
Langfuse vs Braintrust, and Braintrust vs LangSmith
Braintrust is a managed, eval-first platform built around experiments, scoring and a playground. Teams weigh it against Langfuse when they want a managed eval workflow more than open source, and against LangSmith when they want unlimited users on one plan and no LangChain tie-in.
Braintrust's Starter plan is free with unlimited users, and Pro is $249 a month, billed on processed data and scores past the included amount. Its online scoring runs on production traces as they're logged, and Loop is its built-in agent for digging through logs, experiments and datasets.
Self-hosting is Enterprise only: your data plane, Braintrust's managed UI and platform. It accepts OpenTelemetry traces. We found no native multi-turn simulation in its docs. Its earliest dated post is the seed round in December 2023, so it's from the same 2023 wave as the other three.
Show me software that handles prompt history and testing for enterprise AI agents
LangWatch keeps the full version history of every prompt, tests your agents with simulated users before each release, and judges your whole production history when you have a new question. It's open source, and it runs in our cloud, hybrid, or fully on your own infrastructure.
We built it for AI platform teams at enterprises and in regulated industries. Those teams run AI for every product team in the company, and they answer to security, finance and legal for every model call. If you're coming from one of the two, our Langfuse alternative and LangSmith alternative pages go through what changes.
Agent testing for complex agents. Agent testing runs a simulated user through a multi-turn conversation with your agent, and a judge passes or fails each criterion you wrote, with its reasoning. It runs on Scenario, our open-source framework, which we launched in April 2025. Engineers write scenarios in pytest or vitest and run them in CI, and PMs and domain experts write them in the platform without code. It covers voice agents over real audio and multi-turn red teaming too.
Instant Evals. Instant Evals are evals you run over your entire production history instead of a sample, with the question written in plain words. 10,000 conversations get judged in about a minute, at about a hundredth of what a frontier model costs as the judge, and in our benchmark they agreed with human labels more often than Claude Opus 5 did.
Prompt history. LangWatch saves every prompt change as a version you can compare and roll back, with tags for what runs in production or staging and a link from each prompt to the traces it produced. The prompts CLI keeps them in your repo, so a prompt change goes through review like any other code change.
An AI gateway with budgets. The LangWatch AI Gateway is one OpenAI- and Anthropic-compatible endpoint for every model call in the company. Each app, team or person gets a virtual key, and budgets block the request or warn before the provider gets called, with a trace and its cost for every request.
Claude Code and Codex usage and spend. npx langwatch claude or npx langwatch codex sends a developer's sessions to LangWatch, with cost per session, per pull request and per team. Copilot, Gemini CLI and OpenCode work the same way.
Self-hosting, hybrid and enterprise identity. The self-hosted edition runs the same software as LangWatch Cloud and is uncapped without a license. In the hybrid setup we run the app and your traces stay in your own ClickHouse and S3. An Enterprise license adds SSO, RBAC with custom roles, SCIM and audit logs.
On pricing, the Developer plan is free, Growth is per seat plus events, and read-only users don't take a full seat, so the reviewers and domain experts who only read results don't add to the bill.
Migrating between them
OpenTelemetry is the path that works in every direction. Point a second exporter at the new tool, send the same spans to both for a week or two, compare what your team actually opens, then turn the old one off. Prompts and datasets move separately, by export and import.
Old trace history doesn't come along over OpenTelemetry, so it needs an export. Langfuse schedules exports to S3, GCS or Azure in Parquet, CSV or JSON. LangSmith exports Parquet to S3, but only on Enterprise for accounts created after August 3, 2026. Langfuse also publishes a step-by-step guide for moving off LangSmith, and in LangWatch you upload a dataset from a CSV or JSON file, or build one from your new traces.
All three accept OTLP. Langfuse ingests it at /api/public/otel, and its Python and JS SDKs are built on OpenTelemetry. LangSmith takes OTel traces, and an OpenTelemetry Collector can send the same spans to LangSmith and to a second backend at once. LangWatch takes OTLP over HTTP at https://app.langwatch.ai/api/otel/v1/traces, with protobuf or JSON bodies, and the OpenTelemetry guide has the exporter setup for each language. If your code already uses OpenInference instrumentation, you only change where the spans go.
Put this into production with LangWatch.
Trace your agents, run evaluations, and turn failures into repeatable tests.
Frequently asked questions
- Is Langfuse open source?
- Yes. The Langfuse core is MIT licensed and you can self-host it for free with no usage limits. A few enterprise features, like SCIM, audit logs, data retention policies and project-level roles, sit in separate ee directories under a commercial license and need a license key. ClickHouse acquired Langfuse in January 2026 and said the license stays the same.
- Can LangSmith be self-hosted?
- Yes, but only as an add-on to the LangSmith Enterprise plan. It runs in your own Kubernetes cluster with Helm, and you need a license key from LangChain's sales team. Enterprise customers on AWS can also choose BYOC, where LangChain runs the control plane and the data plane runs in your cloud. The SDKs are MIT licensed.
- Is LangSmith only for LangChain?
- No. LangSmith works without any LangChain code: you trace your own functions with the traceable decorator in the SDK, or send OpenTelemetry traces from any framework. It does fit LangChain and LangGraph best, because those libraries send traces to it with almost no setup and the same vendor runs LangSmith Deployment for LangGraph agents.
- How do I migrate from LangSmith to Langfuse or LangWatch?
- Move the traces with OpenTelemetry. Send your spans to the new tool next to the old one for a week or two, compare, then switch the exporter off. Prompts and datasets move separately, through export and import. Old trace history is the slow part: LangSmith bulk export to S3 is Enterprise-only for accounts created after August 3, 2026.
- What is the best LLM observability platform for production?
- It depends on who runs it. For an AI platform team at an enterprise, LangWatch, because tracing, evals, agent tests, an AI gateway and Claude Code and Codex spend come in one open-source platform you can self-host or run hybrid. Langfuse is the open-source choice for tracing and prompts, and LangSmith is the managed choice for LangChain and LangGraph teams.